Wendy Peters · 24 October 2026
Dynamic Content Adaptation Techniques Leveraging User Behavior Insights in Publishing Platforms
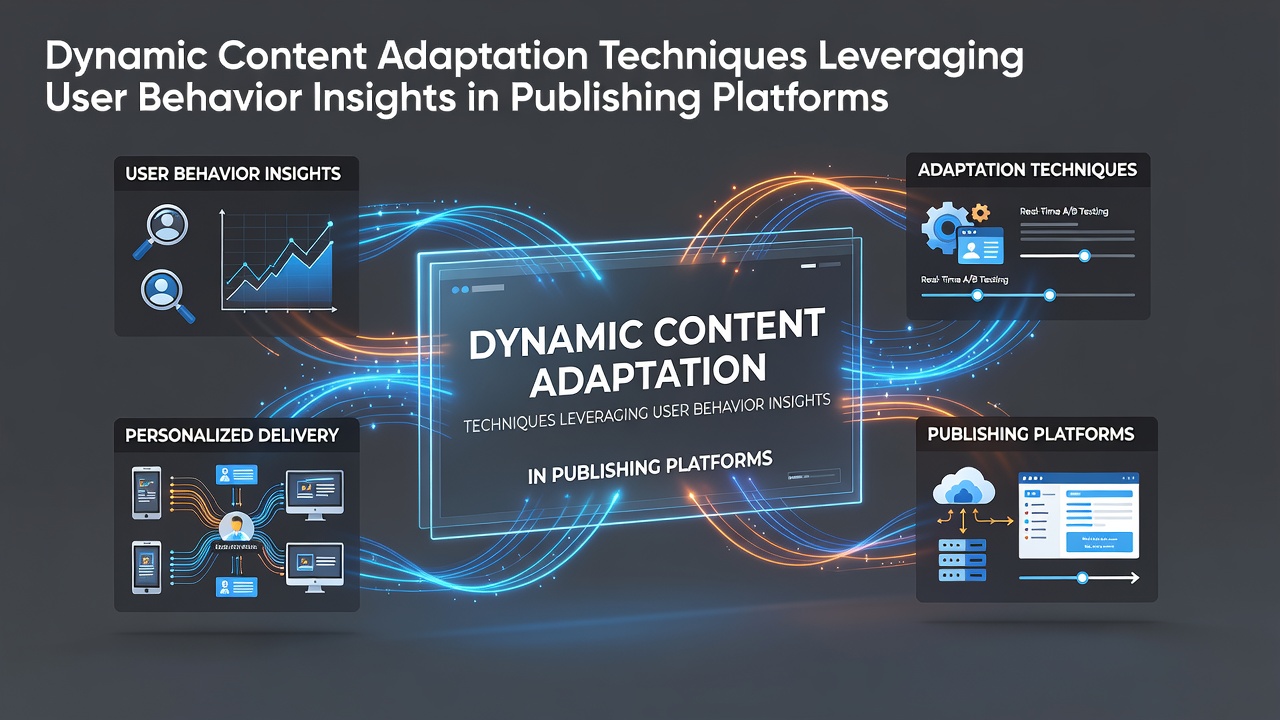
Publishing platforms have shifted toward systems that adjust content presentation in real time based on patterns extracted from user interactions, and data collected across sessions reveals preferences for topic depth, reading duration, and navigation paths. Researchers track these signals through integrated analytics tools that log clicks, scroll depth, and dwell time, then feed the information into adaptation engines designed to reorder headlines, swap images, or modify article summaries without manual intervention from editors. As of October 2026, several major platforms report that such systems now process millions of behavioral events daily, allowing content blocks to change within seconds of a user profile update.
Collecting and Processing Behavioral Data
Platforms gather user behavior insights through a combination of first-party cookies, session recordings, and API calls that pull metadata from mobile applications and web browsers, while machine learning models classify users into segments based on historical patterns rather than static demographics. Observers note that this approach avoids reliance on third-party cookies, which many browsers phased out earlier in the decade, and instead emphasizes on-device processing to comply with privacy regulations across multiple jurisdictions. Studies from institutions in North America and Europe indicate that segmentation accuracy improves when platforms combine explicit actions like bookmarking with implicit signals such as mouse hover duration over specific paragraphs.
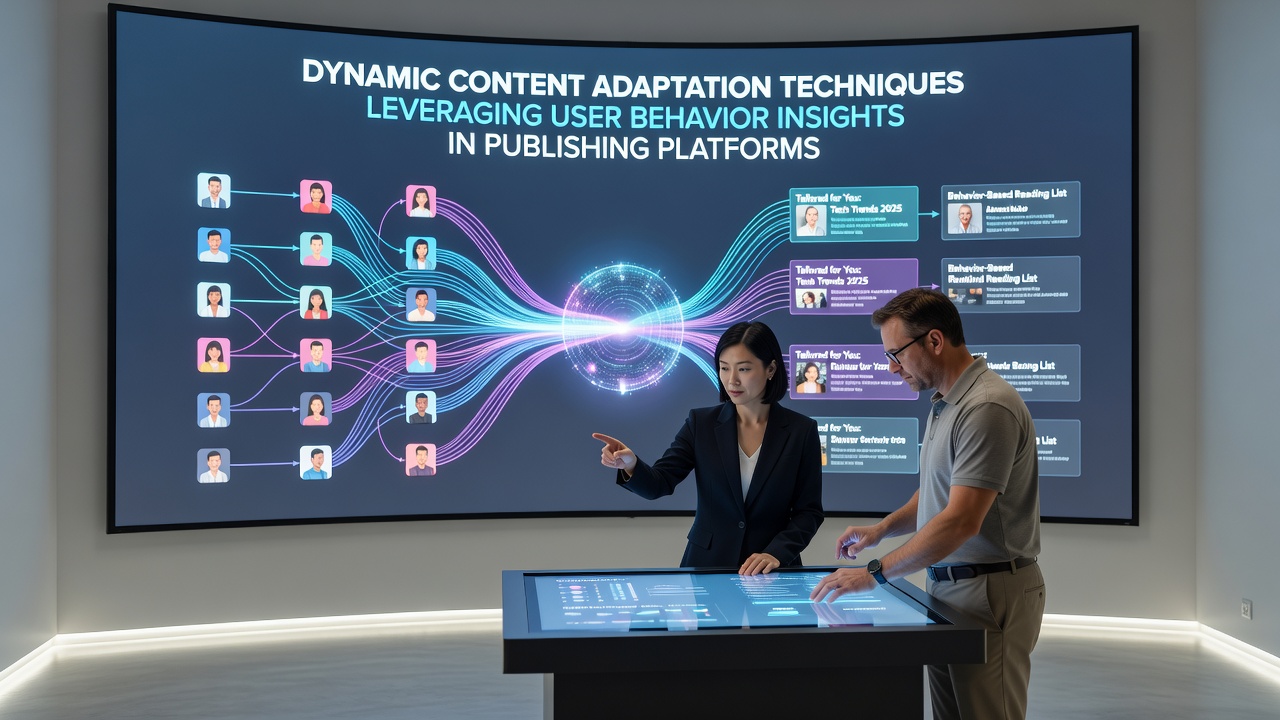
Once collected, the data moves through pipelines that apply clustering algorithms to identify common reading journeys, and these clusters trigger rules that adapt layout elements, font sizes, or even the order of related article suggestions. Experts have observed that platforms using reinforcement learning achieve higher retention rates because the models test small variations continuously and retain only those that increase engagement metrics. In one documented case, a European publishing network adjusted paywall prompts based on exit-intent behavior, resulting in measurable shifts in subscription conversions tracked over quarterly periods.
Core Adaptation Techniques
Dynamic content adaptation relies on several established methods that operate at different layers of the publishing stack. Rule-based systems apply predefined if-then logic derived from aggregated behavior datasets, whereas predictive models forecast the next likely content element a user will engage with and preload variations accordingly. A/B testing frameworks run in the background to validate adaptations at scale, and platforms often combine these approaches so that initial rules give way to learned optimizations once sufficient data accumulates.
Real-time rendering engines sit at the center of these techniques because they assemble pages on demand using templates that accept variables for headline length, image selection, and call-to-action placement. Data indicates that such engines reduce load times when they cache adapted versions for similar user segments, and content delivery networks distribute these pre-rendered variants to edge servers closer to readers. According to guidelines published by the European Data Protection Board, platforms must ensure that behavioral data used for adaptation remains tied to explicit consent mechanisms, which influences how quickly new techniques can roll out in regulated markets.
Integration with Existing Publishing Workflows
Editors continue to set content priorities and brand guidelines, yet the adaptation layer operates beneath those decisions to personalize delivery without altering source material. Workflow tools now include dashboards that surface aggregate behavior trends so teams can adjust editorial calendars based on emerging patterns rather than intuition alone. Platforms that adopted these integrations early report smoother transitions because the systems surface performance data in formats familiar to journalists and producers.
Technical teams handle the backend connections between content management systems and adaptation engines through standardized APIs that pass user context flags without exposing raw identifiers. Research from academic groups in Australia and Canada shows that modular architectures allow platforms to swap adaptation models as new algorithms emerge, reducing the need for full system overhauls every few years. In high-traffic scenarios, load balancing across multiple adaptation servers prevents bottlenecks when user volumes spike during major news events.
Privacy and Compliance Factors
Behavioral insight systems must navigate data protection requirements that differ by region, and many platforms now store processed segments rather than raw event logs to minimize stored personal information. Audit trails document how each adaptation decision traces back to consented data sources, satisfying requirements from oversight bodies in the United States and the European Union. Observers note that transparent explanations of adaptation logic, presented in user-facing settings panels, correlate with higher trust metrics in industry surveys conducted over the past two years.
Security measures include encryption of behavior profiles during transmission and at rest, plus regular penetration testing to protect against unauthorized access that could expose adaptation rules. Platforms also implement differential privacy techniques that add noise to aggregate datasets, preserving overall trend visibility while preventing individual identification. These practices align with standards promoted by research institutions focused on digital media ethics.
Conclusion
Dynamic content adaptation techniques that leverage user behavior insights continue to evolve within publishing platforms through layered combinations of data collection, algorithmic processing, and real-time rendering. Platforms that maintain clear consent flows and modular technical architectures position themselves to incorporate future refinements without disrupting editorial operations. The documented outcomes from various implementations demonstrate that these methods operate within existing regulatory frameworks when privacy controls remain central to system design.